Inside Qualcomm’s Snapdragon X2 Elite Efficiency Core: 3.6 GHz, 128 KB L1I and Shared L2
Snapdragon X2 Elite’s 4-wide, 3.6 GHz efficiency core pairs a large instruction cache with a shared L2, favoring low-power work over peak throughput.
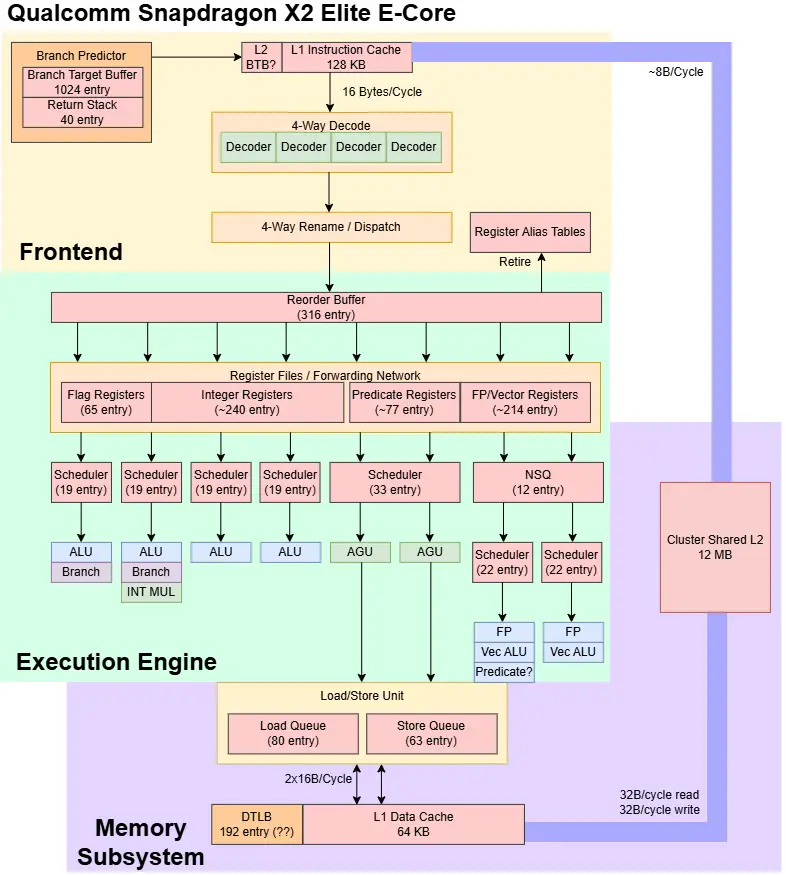
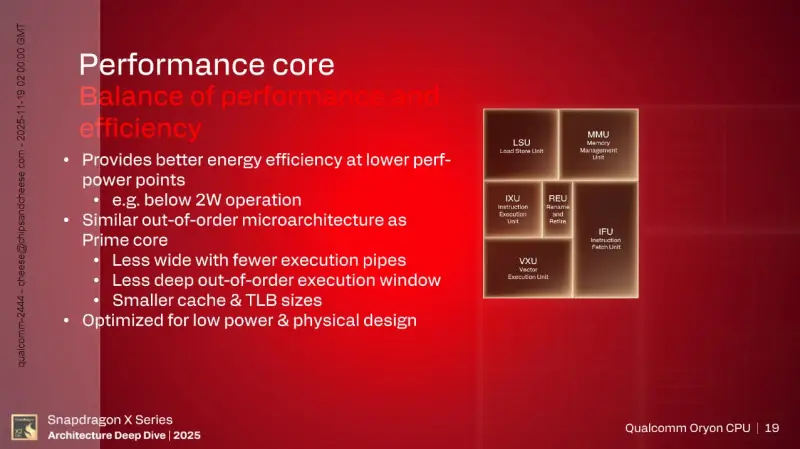
Qualcomm’s Snapdragon X2 Elite adds a distinct efficiency tier to its in-house CPU design. In the 18-core Snapdragon X2 Elite Extreme X2E96100, six “performance” cores sit alongside 12 “prime” cores. The performance label can mislead: these smaller cores are designed for lower power and performance levels, handling background work and lighter applications while the larger cores remain idle. They can also add throughput when a workload uses many threads.
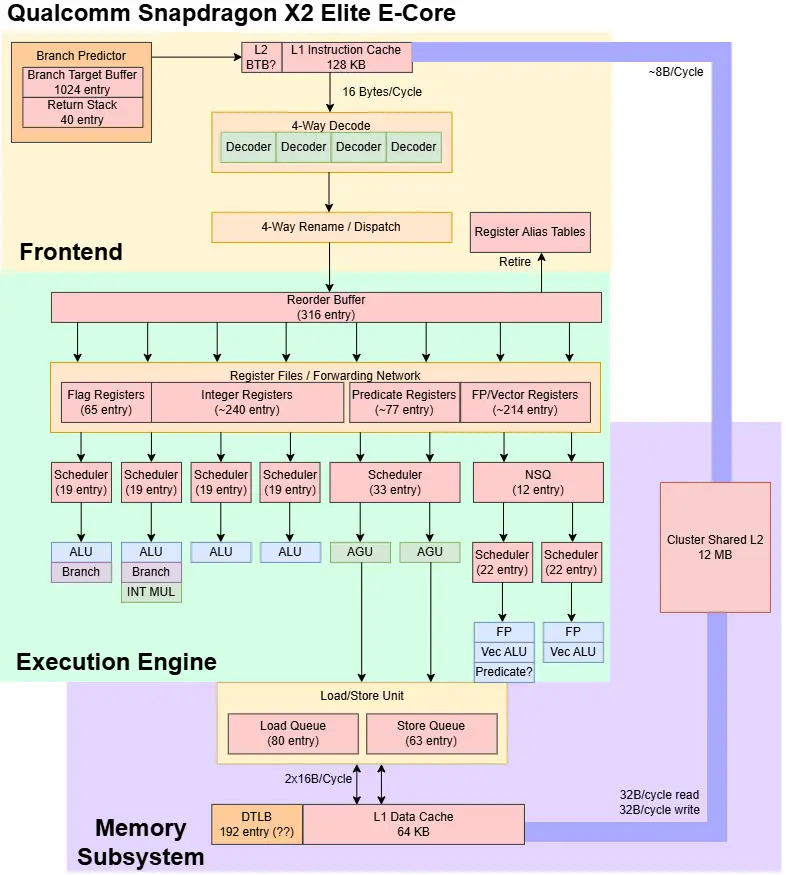
Measurements of the efficiency core in the Asus Zenbook A16 UX3607OA show a design that puts useful cache capacity and substantial scalar resources into a relatively narrow pipeline. It’s a different balance from Qualcomm’s large cores, which the same chip runs at up to 5 GHz and builds nine-wide. The efficiency core is four-wide and clocks at 3.6 GHz. Its value is likely in doing routine work without paying the power cost of a larger core.
Prediction and instruction supply
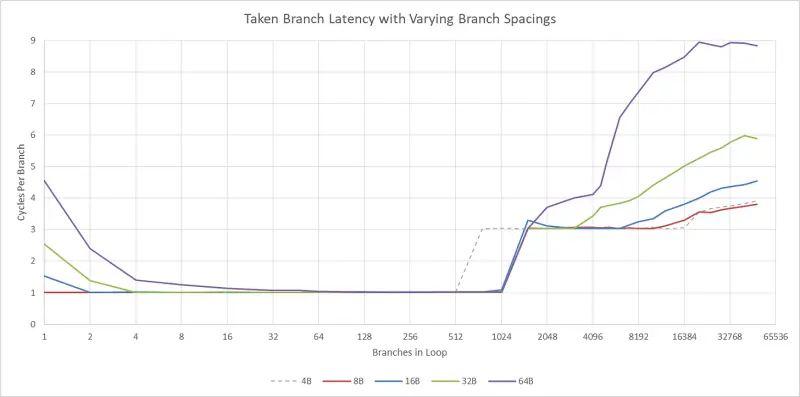
A four-wide, out-of-order core can still spend time and power on work that doesn’t contribute to useful execution. Qualcomm’s branch predictor handles common cases effectively, though its capacity and throughput reveal limits on larger code footprints. Its 1,024-entry branch target buffer (BTB) can deliver predictions for taken branches back-to-back. That’s less throughput than the two taken branches per cycle reported for Intel and AMD’s large cores and Arm’s Neoverse N2.
The BTB appears to operate independently of the L1 instruction cache: measured capacity stays steady as code footprint and branch spacing change. Once a test exceeds the 1,024-entry BTB, throughput falls to one taken branch every three cycles. Performance drops again beyond the 128 KB L1 instruction cache. A second-level predictor tied to that cache, or branch targets calculated as instructions reach the decoder, could explain the results. Either approach would be simpler than a very large second-level BTB, but an instruction-cache miss could then leave the predictor unable to follow taken branches. That may hamper instruction prefetching across large code footprints.
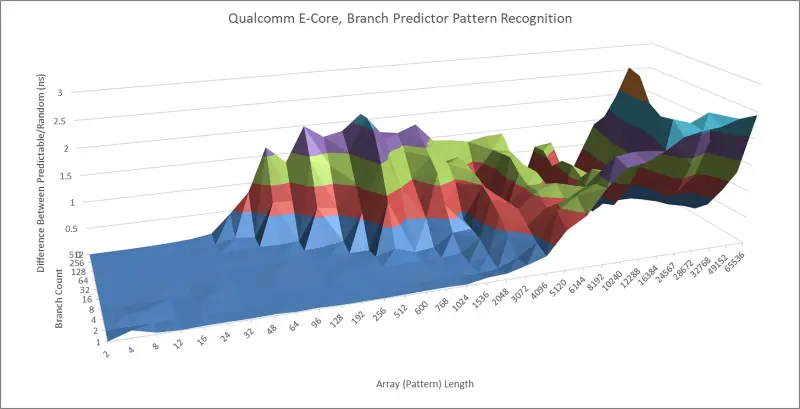
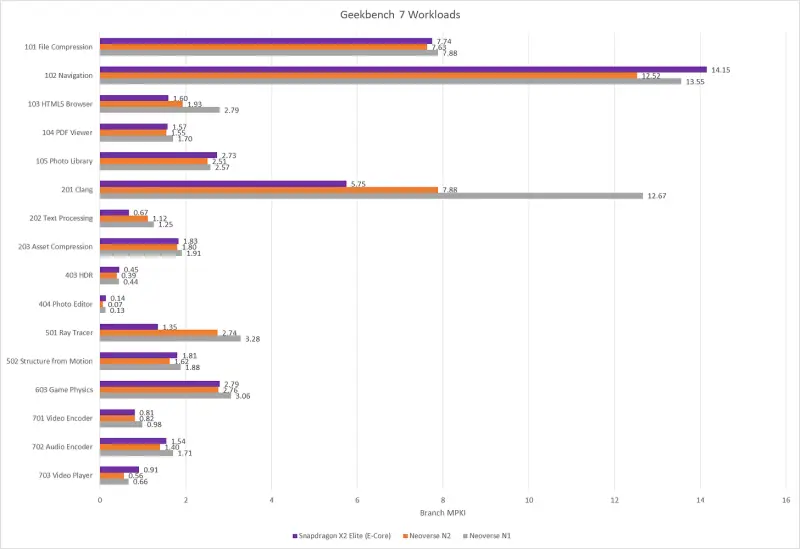
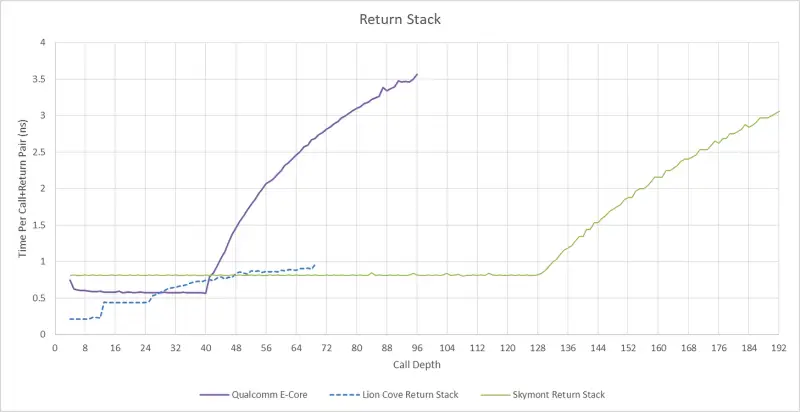
For branch direction, the core tracks long patterns and a substantial number of them: roughly 16,000 patterns with 512 branches in play, or around 1,000 patterns when tracking a single branch. Across Geekbench 7 workloads, prediction accuracy is roughly in line with Arm’s Neoverse N2 and ahead of Neoverse N1. A 40-entry return stack predicts function returns and sustains a call-and-return pair every two cycles. That averages one taken branch per cycle, faster than the return stacks measured on AMD Zen 5 and Intel Skymont.
Capacity sits between Intel’s 128-entry structures in Skymont and Crestmont and the 24-entry structure in Lion Cove. Those sizes aren’t directly comparable without considering what happens on underflow. Some designs appear to use an alternate predictor when the return stack runs out, avoiding a misprediction. On Qualcomm’s core and Intel’s Skymont, the measured taken-branch latency rises beyond a dozen cycles, consistent with a misprediction. Qualcomm’s 40 entries suggest a preference for making underflow uncommon rather than masking it with a fallback path.
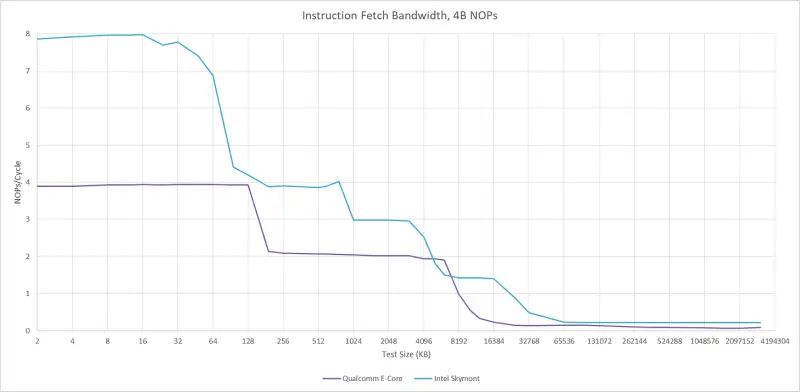
The 128 KB instruction cache is generous compared with the 32 KB and 64 KB caches found in many current designs. Keeping more code close to the frontend can avoid fetching it from L2. When instructions do come from L2, frontend bandwidth is about two instructions per cycle, below what Intel Skymont can sustain from its shared L2. A miss in the CPU’s L2 cache leaves instruction delivery especially constrained.
Dispatch and execution resources
After decoding, instructions become micro-ops and need bookkeeping resources before out-of-order execution. Qualcomm uses this dispatch stage to eliminate some operations before they reach the execution units. Register-to-register moves can be removed at up to two dependent operations per cycle: the renamer updates its register map so multiple architectural registers refer to one physical register. An eliminated move has zero execution latency and doesn’t need a physical register.
There’s a caveat for tightly chained moves. A continuous dependent chain runs at 1.38 moves per cycle, suggesting that some operations miss the elimination path. Spacing the moves with NOPs so each four-instruction decode group contains no more than two moves raises throughput to two per cycle. Independent moves can be eliminated at four per cycle. Even when latency isn’t at stake, avoiding physical-register allocation can leave more room for other instructions in flight.
Small immediate adds can also be eliminated, but under tighter conditions. The core handles up to two per cycle, and the sum of the immediate values in eliminated adds must be 255 or less. For example, adding 254 and then 1 to the same register can qualify; two additions of 128 cannot. Intel’s Golden Cove supports higher throughput and larger immediates. Qualcomm doesn’t give a zero immediate move special treatment, so writing zero to a register still consumes a physical register.
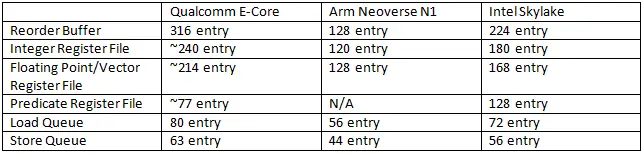
The reorder buffer and register files are sized more like AMD Zen 4 than older four-wide cores such as Intel Skylake and Arm Neoverse N1. Memory-ordering queues are closer to Skylake’s scale, though somewhat larger. For integer work, four arithmetic logic unit (ALU) ports match the core’s four-wide front end. Each port has a 19-entry scheduling queue in a distributed scheduler. Three ports can handle flag-setting operations such as SUBS and CMP; one can execute integer multiplies with three-cycle latency. Two ports can resolve branches, but their peak throughput applies to not-taken branches because taken branches depend on predictor throughput.
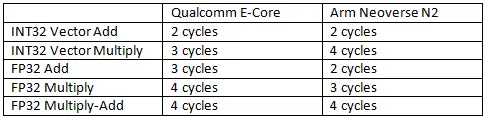
Floating-point and vector operations receive less emphasis, but two execution ports cover common floating-point and integer-vector operations, as well as cryptography instructions such as AESE. Latency is around average for a modern core. The design supports SVE2 and SME, which provide instruction-set extension support across the chip; these are new to Snapdragon X2 Elite, while the earlier Snapdragon X Elite lacked SVE support. Pointer authentication and memory tagging (MTE) are also supported.
SVE uses a 128-bit vector length here. Its contribution is therefore new instructions and predicate support rather than wider vector execution. One floating-point port handles comparisons that write a predicate register. Some predicate operations that don’t use vector registers, including SVE’s while instructions, can issue on an integer port, saving vector-port capacity. The core issues at most one while* operation per cycle, which may mean only one integer port can write the predicate register file. SVE also enables non-contiguous memory accesses through gather and scatter instructions.
Memory access and cache behavior
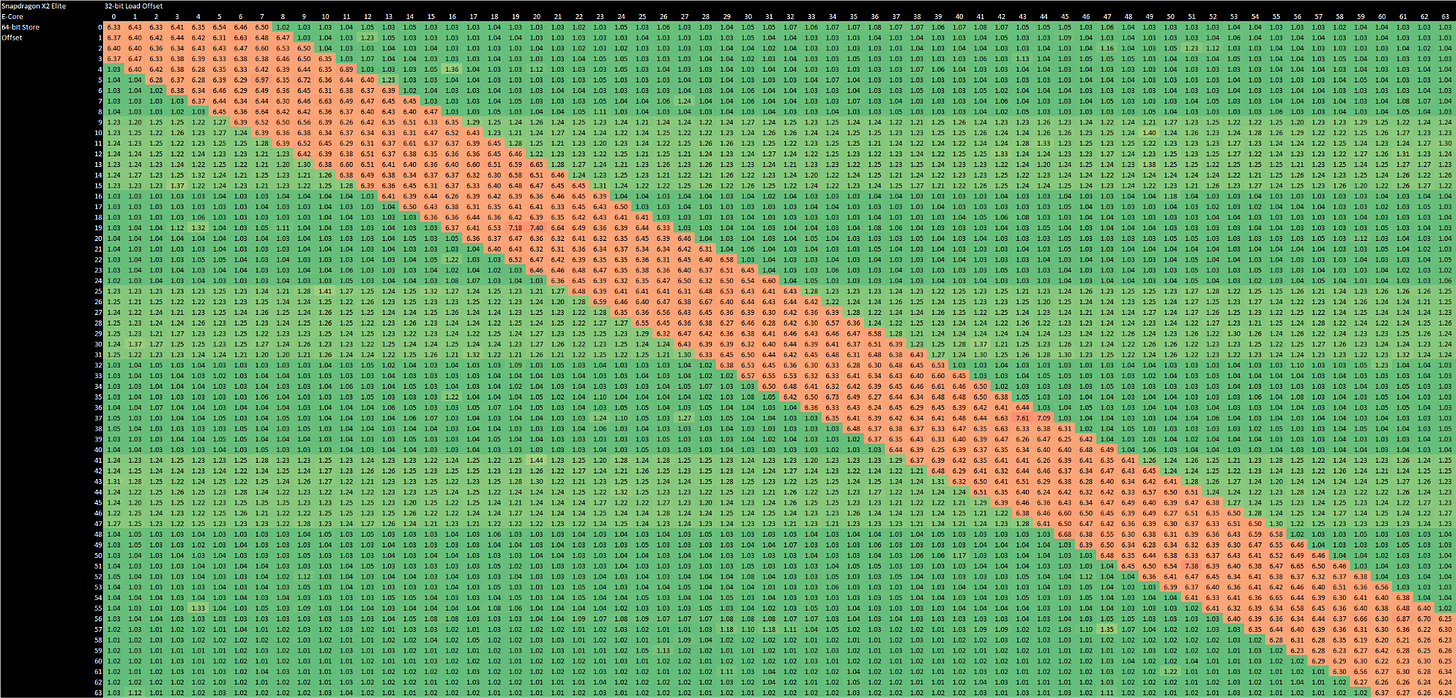
Two memory pipelines can each handle loads or stores. When an older store overlaps a load, store forwarding takes six to seven cycles across the measured alignments. Qualcomm avoids a failed-forwarding penalty for partial overlaps, though it lacks the especially fast exact-address case found on Skymont.
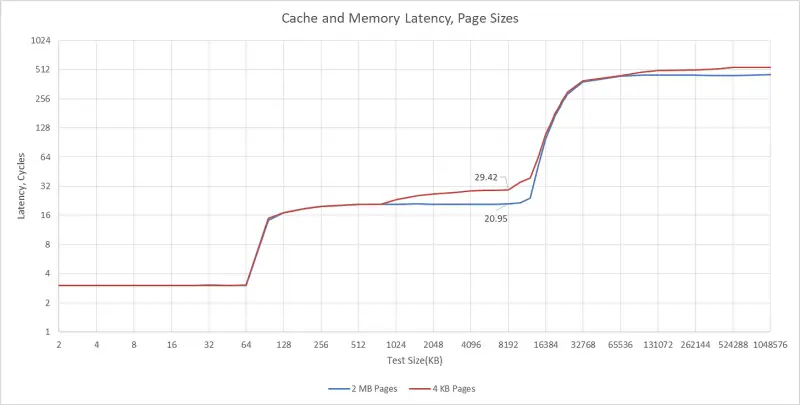
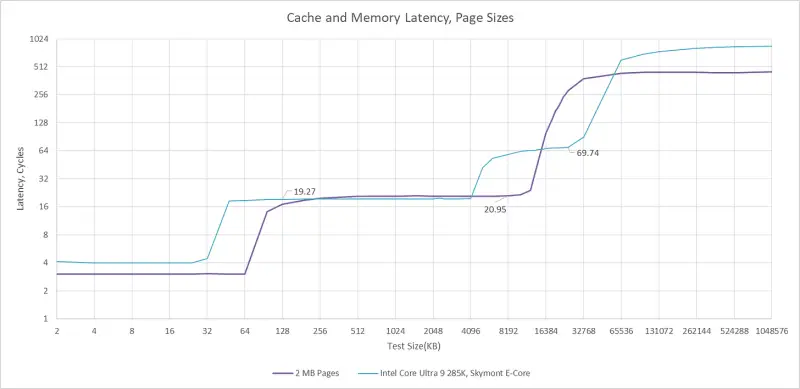
Address translation appears generously provisioned. Qualcomm’s published material gives the larger cores a 224-entry, seven-way L1 data TLB, backed by an 8,192-entry L2 TLB, but doesn’t specify capacities for the efficiency core. Measurements suggest a 192-entry L1 data TLB and an 8,192-entry L2: misses begin increasing beyond a 768 KB test footprint in L1 and 32 MB in L2. An L2 translation takes more than eight cycles, based on latency comparisons using 4 KB and 2 MB pages.
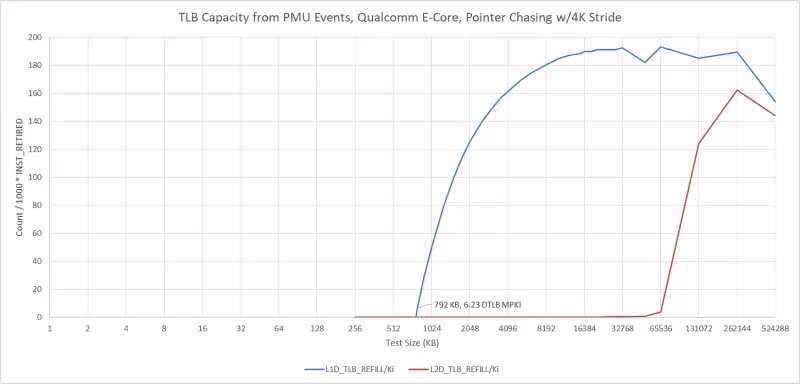
The TLBs support 4 KB and 64 KB pages, but not 16 KB pages. Windows uses 4 KB pages, as does Linux in its usual configurations; Ubuntu also offers a kernel version with 64 KB pages. That makes page-size support a practical compatibility detail for systems that rely on larger Linux pages.
The 64 KB L1 data cache combines capacity with a three-cycle load-to-use latency. Indexed addressing raises that to four cycles. On a miss, data goes to a shared L2 rather than a private mid-level cache on each core. This arrangement resembles Apple’s M1. The L2 takes 21 cycles, just two cycles more than Skymont’s 4 MB shared L2, though Skymont’s higher clock rate gives it lower latency in absolute time.
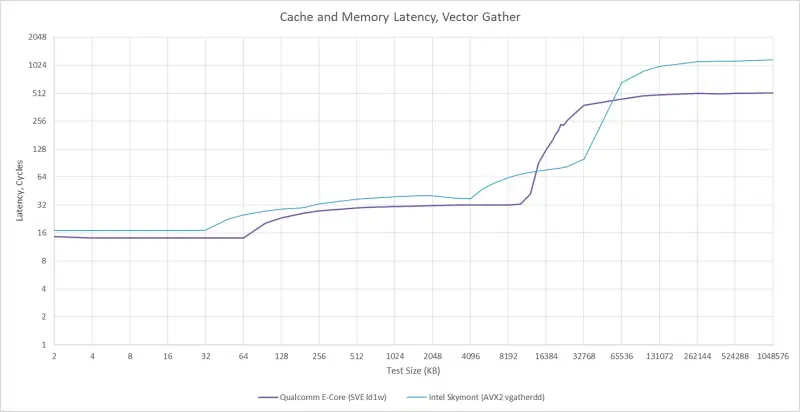
Gather operations illustrate the tradeoff between the SVE instruction set and the core’s memory machinery. A gather accesses non-contiguous addresses with one instruction, but measured throughput is roughly one element per cycle and latency is just under 4 ns, or 14 cycles. There’s no evidence of a combined-gather path that could group elements from the same 64-byte or 128-byte block, as described for Fujitsu’s A64FX and Monaka cores. Gather latency is generally high: Intel Skymont measures 3.7 ns, or 17 cycles, on an L1 data-cache hit.
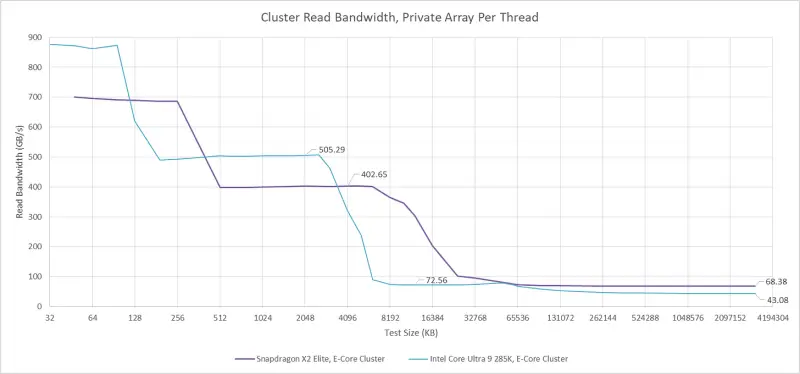
L1 data-cache bandwidth is 32 bytes per cycle, matching the 128-bit vector width and two memory pipelines. A linear read pattern delivers slightly more than 16 bytes per cycle for arrays that fit in L2, with no drop when the array extends to DRAM. The core itself can’t use all the bandwidth its L2 can deliver. Measurements indicate more than 32 bytes per cycle to one core and just over 400 GB/s of read bandwidth across the six-core efficiency cluster. Per-core L2 bandwidth remains around 18 bytes per core cycle under load.
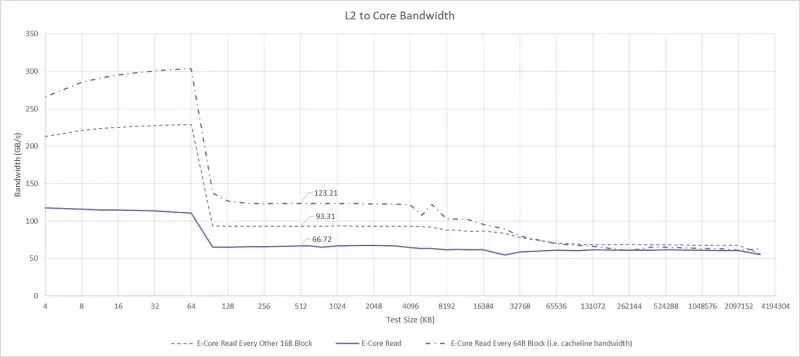
Those bandwidth estimates rely on the cache fetching a full 64-byte line even when a test touches only part of it. Loading only the first 128 bits of each line points to more than 500 GB/s of raw L2 bandwidth, although the cores can’t consume all of that data directly. Skymont’s cluster has smaller caches but more bandwidth per core, feeding a higher-throughput architecture.
A deliberately narrower core
Qualcomm’s efficiency core is modest beside Intel’s eight-wide, 4.6 GHz Skymont or AMD’s Zen 5c, which shares its underlying architecture with a higher-performance counterpart. That doesn’t make it a scaled-down version of Qualcomm’s prime core. The cache hierarchy and execution resources point to a distinct design target: lower-power work where maximum throughput matters less than keeping routine tasks off the larger cores.
Narrower cores also avoid some of the cost and complexity that come with feeding wider pipelines. Renaming, instruction queues and decoding all need more resources as width increases. Those resources can sit idle when a workload doesn’t expose enough parallel instructions to fill the pipeline. Qualcomm’s four-wide, 3.6 GHz choice looks measured: broad enough to run everyday work effectively, yet less demanding than a core built to maximize throughput. The practical test will be whether the chip’s scheduling keeps lightweight work on this cluster while preserving the prime cores for tasks that can use their additional performance.
 AMD Venice Uses 2.5D Packaging to Feed More Bandwidth Into EPYC Zen 6
 CNC Controller Board Design: Interfaces, PCB Specs and Assembly Testing
 Stratasys and Nano Dimension End $42.5 Million Markforged Sale Agreement